LLVM Is the Invisible Engine Behind AI Hardware. Here Is How.
From GPUs to custom AI chips, every major hardware company depends on LLVM and its younger sibling MLIR to turn AI models into running code. Here is what they are and why they matter.

Every time you run an AI model, something has to translate high-level Python into instructions a chip can execute. That something is a compiler. And in 2026, nearly every compiler that matters for AI is built on the same foundation: LLVM.
What LLVM Actually Is
LLVM started in 2000 as Chris Lattner's research project at the University of Illinois. The original idea was simple but powerful: instead of building a separate compiler for every language and every chip, build a shared intermediate layer that any language can target and any hardware can consume.
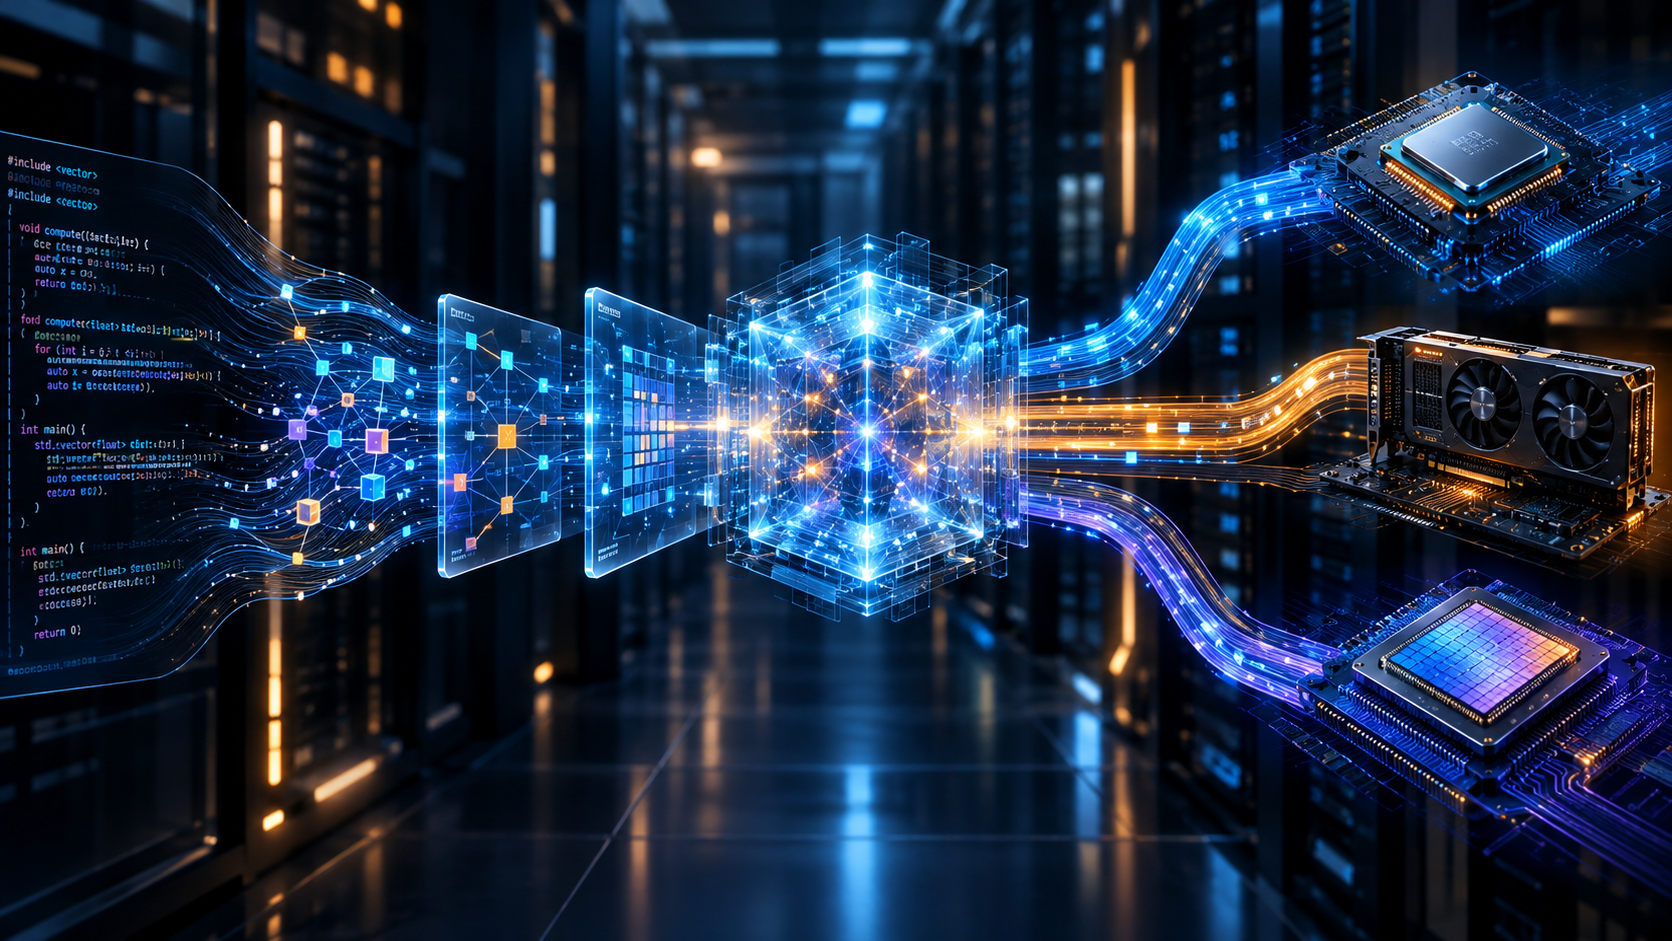
That intermediate layer is LLVM IR (Intermediate Representation). Languages like C, C++, Rust, Swift, and Fortran compile down to LLVM IR. From there, LLVM backends generate optimized machine code for x86, ARM, RISC-V, GPUs, and dozens of other architectures. One IR, many frontends, many backends.
Today LLVM has over 2,100 active contributors, 35.5 million lines of code, and generated 37,486 commits in 2024 alone. It is licensed under Apache 2.0 and governed by the LLVM Foundation.
Why AI Needs a Compiler
AI workloads do not run on magic. A PyTorch model is Python code that eventually needs to become matrix multiplications on specific hardware. Someone has to map tensor operations to GPU warps, or tile computations across a TPU's systolic array, or vectorize inference on a CPU's AVX-512 units.
That mapping is compilation. And it is getting harder, not easier. Every new AI chip (Google TPU, AWS Inferentia, AMD Instinct, Intel Gaudi, Cerebras, Groq, dozens more) needs its own compiler backend. Without a shared framework, every chip vendor would build from scratch, and every ML framework would need custom integration with every chip.
LLVM solved this problem for traditional languages. But AI has a different problem.
The Problem LLVM Could Not Solve
LLVM IR was designed for C-like languages. It operates at the level of integers, floats, pointers, and control flow. AI compilers need to reason about tensors, convolutions, attention heads, and memory hierarchies that span multiple chips.
By 2017, the AI compiler landscape was fragmenting fast. TensorFlow had XLA. Facebook had Glow. Apache had TVM. Each framework built its own compiler stack with its own intermediate representations, its own optimization passes, and its own hardware abstractions. None of them could share infrastructure.
Chris Lattner, who had moved from Apple to Google, saw the pattern. He had solved this exact problem before with LLVM. Now he needed to solve it one level higher.
MLIR: The Compiler Framework for AI
MLIR (Multi-Level Intermediate Representation) started in 2018 at Google, led by Lattner, Mehdi Amini, and River Riddle. It became an official LLVM subproject in 2019.
The core insight is right in the name: multi-level. Instead of a single IR at one abstraction level, MLIR supports multiple IRs (called "dialects") that can coexist and transform between each other. A high-level dialect can represent full tensor operations. A mid-level dialect handles loop tiling and memory placement. A low-level dialect maps to hardware instructions.
Each dialect is a self-contained namespace of operations and types. TensorFlow has its own dialect. So does the GPU programming model, linear algebra operations, and standard control flow. You can write optimization passes that work at any level, and you can mix dialects freely.
This solves the fragmentation problem. Instead of every AI framework building everything from scratch, they build dialects that plug into the same infrastructure and share the same optimization framework.
Who Builds It: The Corporate Backbone
LLVM is open source, but it is not a hobby project. The heaviest investment comes from companies that depend on it for their hardware and software platforms.
The LLVM Foundation's Diamond sponsors tell the story: AMD, Apple, Google, and Qualcomm. At Platinum: Arm, Fastly, Huawei, Meta, and NVIDIA. Gold sponsors include AWS, Fujitsu, Microsoft, and Sony.
Looking at actual code contributions and strategic focus:
Google is the largest contributor to MLIR specifically. Google built MLIR for TensorFlow and XLA (its domain-specific compiler for TPUs), and continues to drive the MLIR ecosystem. Google also uses LLVM/Clang for Android, Chrome, and its internal C++ codebase.
Apple has been central to LLVM since Lattner joined Apple in 2005. Apple funds Clang (the C/C++/Objective-C frontend), built Swift on LLVM, and uses it across Xcode, Metal (GPU shading), and all of its operating systems. Apple is consistently one of the top contributors by commit volume.
NVIDIA maintains the NVPTX backend that compiles CUDA code to run on NVIDIA GPUs. Every CUDA application, including virtually all AI training today, flows through LLVM.
AMD maintains the AMDGPU backend for its Instinct and Radeon GPUs, plus the ROCm software stack. AMD is one of the top individual commit contributors through engineers like Matt Arsenault and Craig Topper.
Intel drives the x86 backend optimizations, the oneAPI/SYCL compiler stack, and the SPIR-V backend for its GPU and accelerator products.
Qualcomm recently acquired Modular, the company Lattner founded after leaving Google. Modular built Mojo (a Python-superset language for AI) and the MAX inference engine, both heavily built on MLIR. The acquisition, completed in July 2026, made Lattner Qualcomm's EVP of Advanced AI Software.
Meta contributed BOLT, a post-link binary optimizer that is now part of LLVM, and uses Clang/LLVM across its infrastructure.
Where MLIR Is Used Today
MLIR has moved well past the research phase. Here is where it runs in production:
TensorFlow/XLA uses MLIR as its compiler backbone, converting TensorFlow graphs into optimized code for Google TPUs, GPUs, and CPUs.
torch-mlir bridges PyTorch with MLIR, allowing PyTorch models to target any MLIR-based backend. This is the path from PyTorch to custom hardware.
Triton (by OpenAI) uses MLIR dialects to compile GPU kernels. Triton lets researchers write GPU code in Python and get performance close to hand-tuned CUDA.
IREE (Intermediate Representation Execution Environment) is a compiler and runtime from Google that takes ML models through MLIR to run on CPUs, GPUs, and embedded devices.
Mojo/MAX from Modular (now Qualcomm) is built entirely on MLIR. Mojo compiles through MLIR dialects to generate optimized code for any target hardware.
TPU-MLIR by Sophgo uses MLIR to compile models for its AI accelerator chips.
MLIR-AIE from AMD/Xilinx targets AI Engine processors in AMD's Versal adaptive SoCs.
Why This Matters for AI Infrastructure
The AI hardware market is fragmenting. NVIDIA dominates training, but inference is splitting across GPUs, CPUs, custom ASICs, and edge devices from dozens of vendors. Each of those chips needs a compiler. MLIR means they do not each need to build one from zero.
For infrastructure architects, MLIR is the layer that makes hardware choice a deployment decision instead of a rewrite. A model compiled through MLIR can target different backends without changing the model code. That is what breaks vendor lock-in at the silicon level.
Chris Lattner built LLVM to unify compilers. Twenty-five years later, MLIR is doing the same thing for AI. The companies building the future of compute, from Google's TPUs to NVIDIA's GPUs to Qualcomm's edge AI, are all building on this shared foundation.
The compiler is invisible. The impact is not.
Related Reading
- Beyond GPUs: How Broadcom Custom Silicon Is Reshaping AI Infrastructure
- AMD Crosses $1 Trillion: The Technical Architecture Behind the Only Real Challenger to NVIDIA's AI Dominance
- AI Was Supposed to Kill the CPU. Instead, It Is Rewriting the Data Center
References
- The LLVM Compiler Infrastructure Project↗
- MLIR: Multi-Level Intermediate Representation↗
- LLVM 2024 Code Activity - Phoronix↗
- LLVM Foundation Sponsors↗
- Chris Lattner - Wikipedia↗
- Qualcomm Acquires Modular - Qualcomm↗
- Triton: An Intermediate Language and Compiler for Tiled Neural Network Computations↗
- IREE - MLIR-based ML Compiler and Runtime↗
Discussion
No comments yet. Be the first to start the discussion.
Related Articles
The AI Dictionary: Every Term You Need to Know, Explained Simply
A plain-language glossary of AI terms from the absolute basics to advanced concepts. No jargon walls, no assumptions. Every term explained so anyone can understand it.
AIJev and the Rise of Decision Models: What Changes When AI Returns Probabilities Instead of Text
TypeSafe AI's Jev returns typed decisions with probabilities instead of text. A technical look at what is new in the approach, a fair comparison with structured-output LLMs, what independent research says about calibration, and what it takes to self-host Jev-class open models.
AITwo Ways to Win an AI Race: Own the Model, or Spread It
The US optimizes for owning its best frontier models. Several Chinese labs release near-frontier weights instead. Two different bets about turning AI capability into power, and it is not yet clear which one wins.
Stay in the loop
Get new articles on infrastructure and AI delivered to your inbox. No spam, unsubscribe anytime.